If you look at how losses actually play out in a data center, they tend to build through a sequence rather than come from a single trigger.
Say you lose power or performance in one system, something else doesn’t respond the way you expected, recovery takes longer than planned and the impact spreads across the site. By the time you see the full effect, you’re already dealing with downtime and a more complex recovery.
That’s why it helps to think about risk in terms of how your systems behave together. Once you understand how failure starts and how it develops, you can make more targeted decisions on design, operations, as well as insurance.
In this insight, based on our multi-disciplined Outsmarting Uncertainty webinar on data centers, we offer practical steps for data centers to achieve that deeper and more realistic view of risk so you’re better placed to reduce losses and get more value from risk transfer.
Why do generic hazard assessments fall short for data centers?
A location-level hazard view will tell you where exposures exist, but it won’t tell you how your site performs when something goes wrong.
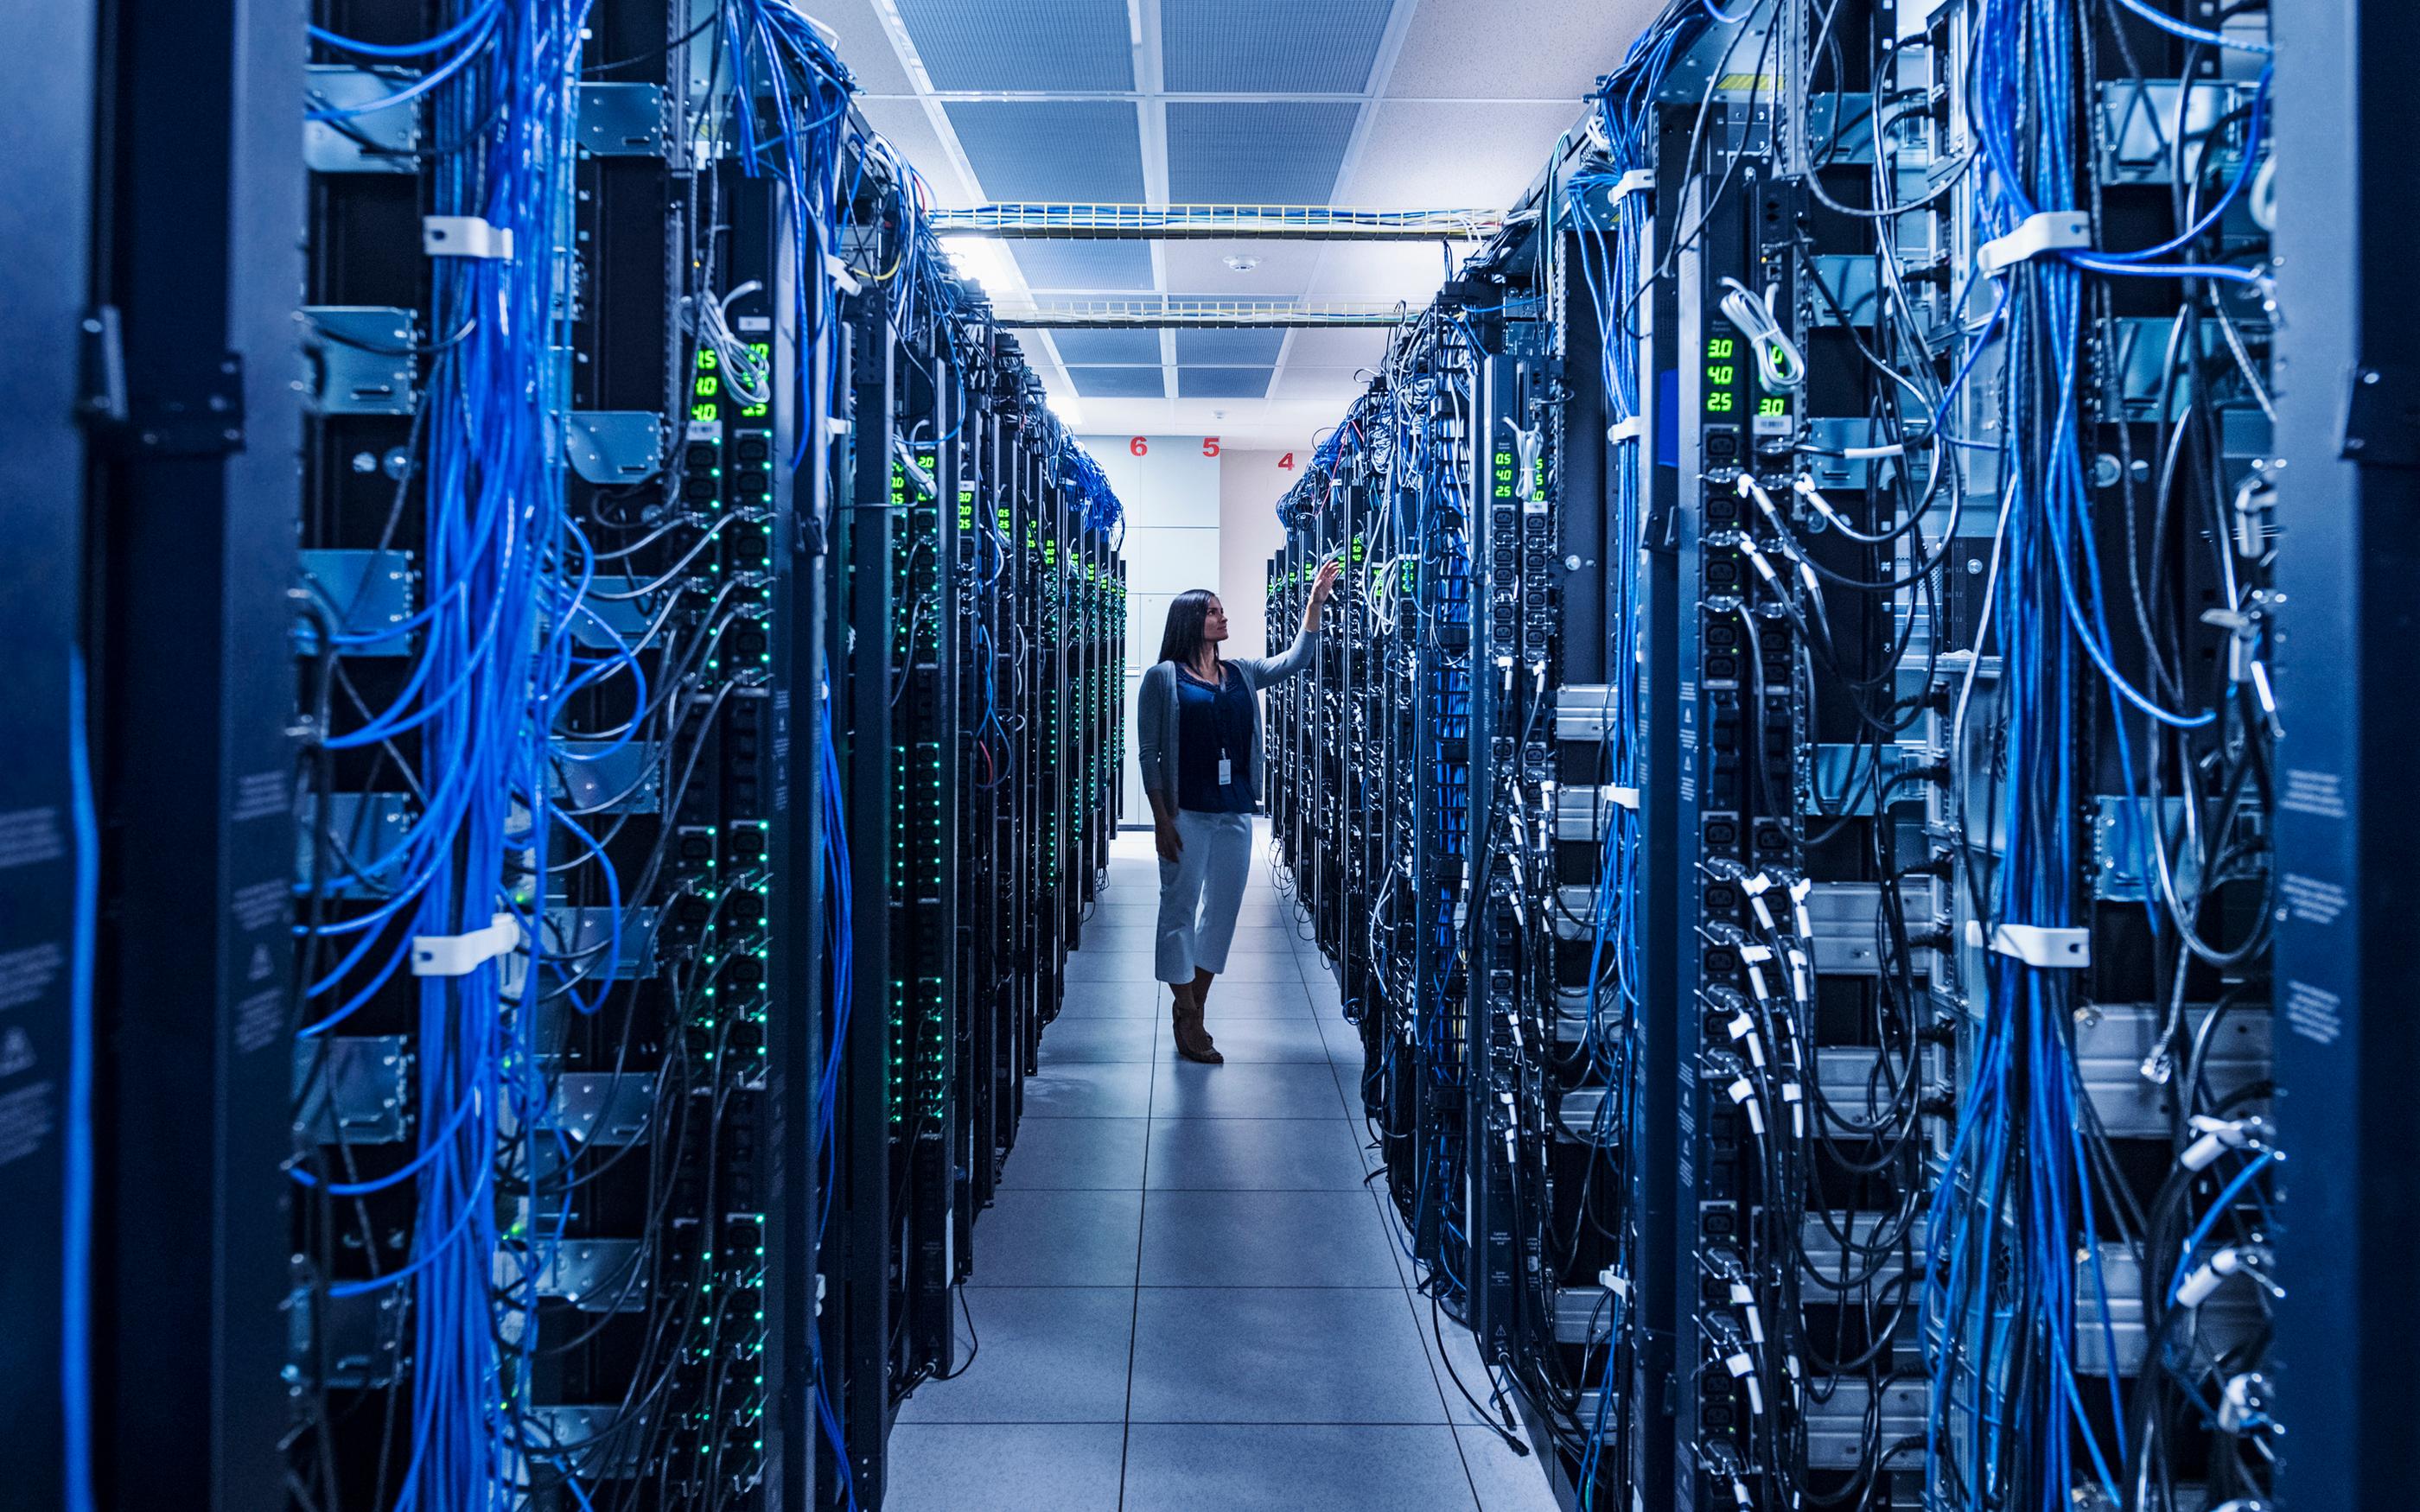
Your facility runs on connected systems where power, cooling, controls and recovery all depend on each other. When one of those systems fails, the effect moves through the rest and can impact your entire digital infrastructure facility.
Technology changes also bring in failure modes that don’t show up in historic loss data. For example, higher density, different cooling approaches and new power configurations all change how your site could behave under stress.
That means you need to break the system down and work through it step by step. First, look at how power enters the site, how cooling behaves under load, how control systems respond and how recovery takes place. Then, you connect those steps and see how they interact.
By doing this, you will learn more about your real exposure than a high-level hazard map and equip you to make more informed decisions on balancing risk reduction, retention and transfer.
What drives downtime in data centers and digital infrastrucutres?
When you map downtime pathways from trigger to recovery, delays become easier to identify, address and mitigate against.
Downtime usually follows a chain of events. Understanding that chain gives you a clearer starting point for reducing loss.
For your digital infrastructure facility, power continuity is central, but it doesn’t stop at your backup systems. If something happens upstream, at a substation or in the wider grid, you can end up outside the conditions your backup was designed for.
Physical damage from fire and smoke may stay contained, but smoke and residue can increase the scope of impact and extend the recovery process.
You also see single points of failure in places that are easy to miss. A switchgear configuration, a cooling loop or a dependency on a single vendor can cut across redundancy.
How do dependencies outside your fence line affect data center losses?
Your site depends on infrastructure outside of your fence line and beyond your control, but you can’t ignore them as you develop your most effective approach to managing and transferring risks for your data center.
For example, power supply, water systems, telecom routes, access roads and vendor support all sit outside the boundary of your facilities.
When disruption affects a region, these dependencies can fail at the same time. Mapping these connections clearly helps you identify what supports day-to-day operations and what you rely on during recovery. You can then test how those systems behave under stress.
For example, consider what happens if the same event affects your site and the infrastructure that feeds it. Or if access routes limit the ability to bring in support or equipment during recovery. These factors can extend downtime even when the primary incident is contained.
How do you reduce loss before transferring data center risk?
The starting point is to test how your systems behave when conditions move outside normal operation.
First, look at power beyond your site boundary, checking how cooling performs under sustained heat and reviewing water and fire scenarios in terms of how recovery plays out, rather than how damage occurs.
Next, connect those scenarios to business impact. Define what downtime means in terms of revenue, service delivery and contractual performance.
Get better value from your insurance by keeping up-to-date documentation and a recovery plan to support this work. Keep accurate records of system design, maintenance and testing. Build recovery plans that show how teams assess damage and bring systems back online. Run through those plans so they reflect real conditions to cut the scale of potential disruption and shorten recovery time.
You can then seek insurance structures that match these realities.
How do you structure efficient data center insurance using real loss scenarios?
When you understand your loss profile you can fit your insurance more precisely to these losses.
Be ready to work with a range of outcomes rather than a single value using probable maximum loss and maximum foreseeable loss as reference points, then look at how different scenarios affect your business. This is about helping you decide how much risk you want to retain and how much you want to transfer in line with your tolerance. It also helps you separate construction risk from operational risk, which matters when it comes to structuring your cover in the optimal way.
You can align limits, retention and structure with how your site actually performs.
Where to start with data center loss prevention
Start with one pathway and work through it in detail.
Think about power loss: what triggers it, how do systems respond and what does recovery involve? Speak to the people who operate the site and use their experience to test your assumptions.
How do your cooling systems perform: overheating can damage hardware or force shutdowns. What about hardware failures where server, storage or network equipment breaks down.
By looking at the detail these kinds of process will tell you where exposure sits in practice and where improvements will have the most impact.
From there, you can build a more complete view across other pathways and support better decisions on the key factors central to long-term resilience: design, operations and insurance.
To get a more connected view of the risks to your data center’s long-term performance, get in touch with our team of specialists.
Find out more, watch our Outsmarting Uncertainty data center webinar and get in touch.
Authors
Contacts
Get access to our data centers webcast replay
Outsmarting Uncertainty
Explore how businesses can solve the risk and insurance problems they are currently facing.